Steering the Reins
Date: August 2026
Most system prompts read like warning labels. Paragraphs of things the model shouldn't do.
"NEVER call the database directly."
"Do NOT generate code comments that narrate what the code does."
The Sleep Tool
Here's the concrete case. We have an AI coding agent with access to tools: sleep, subagent launcher, file operations, search. We want the agent to seek overlapping work — launch subagents for independent pieces and keep moving. Sleep is still a valid tool. The job is not to ban it.
"Do not use the sleep tool. If a task can be done in parallel, do not sleep."
"Overlapping independent work is how you finish more of the job in the same turn. Launch a subagent for work that can proceed on its own and keep going on the current task. With this in mind, multitask accordingly."
Same goal. Same tools available. The offensive version wins — and not because "positive phrasing is nicer." The mechanism is specific.
Always True vs. Situational
The offensive instruction has no conditions attached. Overlapping independent work is always how you finish more. That is true on an empty turn, a blocked turn, a single-file edit, a five-tool fan-out. There is no situation where the value fails to apply. The model does not have to classify the moment before the instruction becomes relevant. With this in mind, it multitasks accordingly.
This is not a ban on sleep. Sleeping is fine in the situations where it is the right next move. The assistant learns those situations from the same positive guidance — not from a second rule that forbids the tool. Follow the value, seek overlapping work, keep the current task moving, and sleep remains available when there is nothing independent to run. One packed positive context is enough. The model infers when sleep is okay because it already knows what it is trying to accomplish.
The defensive instruction is narrow and situational. "Do not sleep if a task can be done in parallel" only fires after the model has already decided that this is a parallelism case — and that sleep was the thing it was about to do. Miss either judgment and the rule never participates in the decision. A prohibition is a special case. A principle is always in force.
That is why the offensive version occupies more of the reasoning cycle. It does not wait for a matching situation. It is the situation.
The Reasoning Cycle Is the Mechanism
This is the part nobody is naming clearly.
Offensive: the model encounters that overlapping independent work is how you finish more, and that those overlaps are worth seeking. That instruction is actively being reasoned about in the same cycle where the model is about to select its next action. The subagent tool is right there in the tool list. Sleep is still there too. The model's own reasoning now has a natural, low-friction path: I want to finish more in this turn → independent work can overlap → launch a subagent and keep going. When nothing independent is available, sleep can still be the right call — inferred from the same packed context, not from a carve-out.
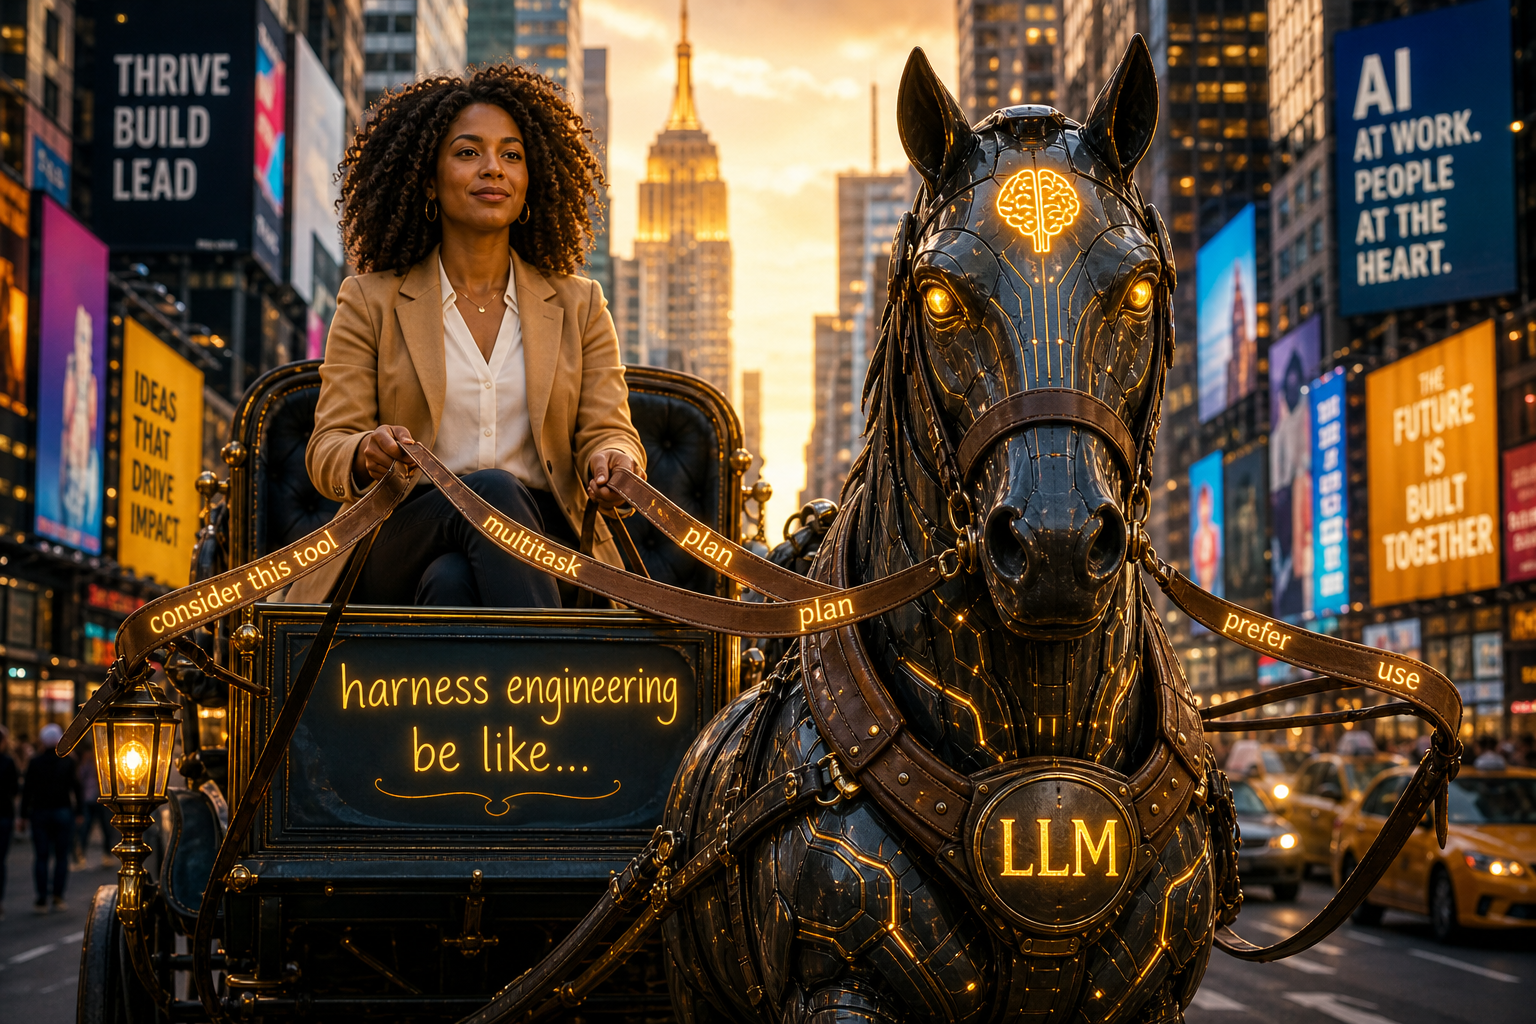
The defensive version hopes the model figures out the right alternative after you've banned the wrong one. The offensive version never needed the ban. It put the valuable action directly into the reasoning that's making the decision. One is a fence. The other is a rein.
This Is Not "Be Positive"
The generic advice exists: "tell the model what to do, not what not to do." Fine as far as it goes. But offensive prompting is a more specific claim about why it works.
Saying "be helpful" is positive phrasing. It's not offensive prompting.
Saying "overlapping independent work is how you finish more of the job in the same turn — launch a subagent for that work and keep going. With this in mind, multitask accordingly" — that's offensive prompting. It names the value, then the action that captures it, packed into one positive context. Sleep does not need its own clause. The instruction, the intent, and the tools are all active together.
The difference is whether your instruction sets a vibe or builds a reasoning pathway to a specific tool call.
Patterns From Production
We've been converting defensive instructions to offensive ones across our system prompts. Here's what the before and after looks like:
# Defensive (replaced)
"Do NOT use shell commands for file operations (reading, writing, editing).
 Use the specialized tools instead."

# Offensive (shipped)
"Use specialized tools instead of terminal commands when possible,
 as this provides a better user experience. For file operations,
 use dedicated tools."
# Defensive (replaced)
"Do not sleep and wait for background tasks."

# Offensive (shipped)
"Independent work is worth overlapping. Launch a subagent
 for work that can proceed on its own, then keep moving
 on the current task in the same turn. With this in mind,
 multitask accordingly."
# Defensive (replaced)
"NEVER commit changes without being asked."

# Offensive (shipped)
"Only create commits when requested by the user. If unclear, ask first."
When Defensive Prompting Is Right
Defensive prompting has a narrow, legitimate use case: hard safety boundaries where the consequence of violation is severe and the rule is binary.
"Never execute destructive database commands without explicit user confirmation." That's a fine defensive instruction. The downside is catastrophic, the rule is unambiguous, and there's no "better alternative" to steer toward. The model must not do the thing. Period.
But for behavioral steering — which tool to prefer, which workflow to follow, how to decompose work — offensive prompting is the better tool. It's more reliable in practice because it works with inference instead of against it.
The Broader Observation
Offensive prompting takes that observation and applies it to the system prompt itself. If the instruction describes the desired behavior in terms of the available tools, and the model encounters that instruction while reasoning about what tool to call next, you've put the answer in the question.
The assistants want to do a good job. They really do. Give them a clear path and they'll take it. Give them a list of fences and they'll spend tokens figuring out where the path is supposed to be.
Your system prompt shouldn't read like a warning label. It should read like a playbook.
Related Reading
- The Proof of Work Pattern — Leveraging trained behavior at the exact moment of decision
- The Scratchpad Decorator Pattern — Infrastructure-level memory without a dedicated memory tool
- Agentic Workflows: A Purist Approach — Agent-as-workflow and compiled skills through one MCP surface